Prompts Lean provers with tactic-skeleton prefixes on miniF2F-test and checks every generated proof by compiling it with Lean 4 against a pinned Mathlib environment.
Abstract
RL-trained Lean theorem provers mode-collapse at inference time: on miniF2F-test with DeepSeek-Prover-V1.5-RL, doubling the i.i.d.\ sampling budget from $k{=}32$ to $k{=}64$ produces zero additional solved theorems (42/244 in both cases). A fixed schedule of 15 tactic skeletons breaks this plateau and recovers a $+45%$ relative improvement at $k{=}16$ (mean $Δ= +12.3 \pm 4.2$ theorems across $n{=}3$ seeds, sign preserved in every seed). A controlled diversity ablation rules out the prompt-diversity confound: tactic skeletons help, paraphrases match the baseline, and irrelevant Lean comments actively degrade. A leave-one-out formalization-difficulty stratification reveals a structural-content gradient across the three perturbations. The phenomenon is RL-specific: V1.5-Base proves zero theorems regardless of intervention, identifying RL as the stage that creates the proof capability which subsequently collapses; extending to two additional 7B Lean provers, RL-trained DeepSeek-Prover-V2-7B contributes $+3$ frontier solves no i.i.d. baseline can reach despite a flat aggregate, while SFT-trained Goedel-Prover does not ( $-10.0$ $\pm 4.4$ theorems, $n{=}3$, sign preserved every seed). Inference-time structural diversity is a cheap, complementary axis for RL-trained provers, orthogonal to scaling model size or training compute.
Problem
RL-trained Lean theorem provers mode-collapse at inference time. With DeepSeek-Prover-V1.5-RL on miniF2F-test, raising i.i.d. sampling from k=32 to k=64 solves no additional theorems. The question is whether cheap inference-time structural guidance can recover performance under a fixed budget.
Approach
Each query pairs the theorem statement with a tactic skeleton, a prefix of tactics such as simp, intro or constructor, drawn from a fixed schedule of 15 skeletons. The model completes the proof after the skeleton. Each attempt is compiled with Lean 4 against a pinned Mathlib environment with a 60-second timeout, and any output containing sorry counts as a failure. Ablations swap skeletons for paraphrases or irrelevant Lean comments, and the comparison is extended to V1.5-Base, DeepSeek-Prover-V2-7B and the SFT-trained Goedel-Prover.
Results
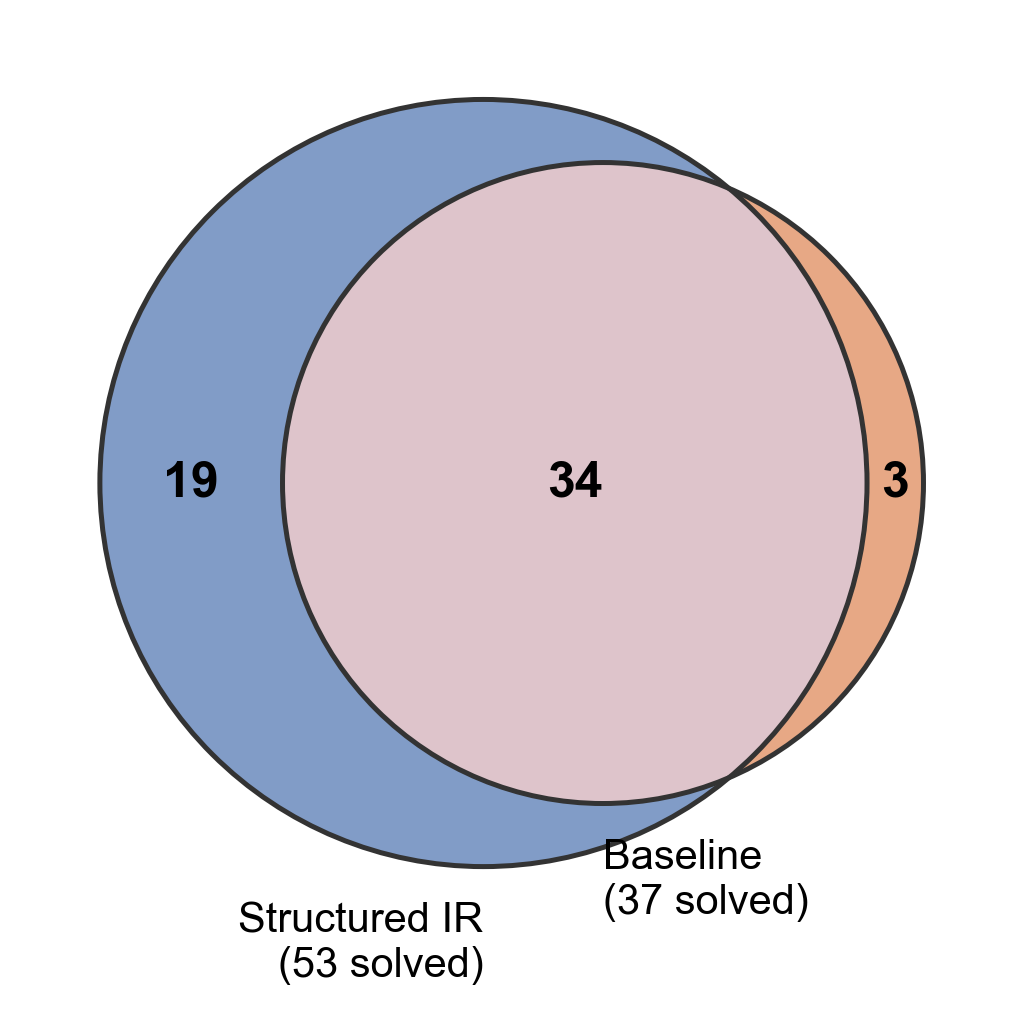
At k=16, skeletons raise solved theorems from 37 to 53 of 244 (+43%, McNemar p<0.001), with 19 unique solves versus 3 for the baseline. Paraphrases match the baseline and irrelevant comments degrade it. The benefit appears RL-specific: Prover-V2-7B gains 3 frontier solves, while SFT-trained Goedel-Prover loses about 10 theorems.
Figure 1: Venn diagram detailing the overlap of solved problems
Method
Solved (N)
Pass@16 (%)
Relative Gain
Baseline (Unguided)
37 / 244
15.16%
-
Structured IR
53 / 244
21.72%
+43.2%
miniF2F-test performance with DeepSeek-Prover-V1.5-RL, k=16, 1024 tokens