LLM agent writes Lean 4 proofs, uses the sorry placeholder to isolate failing subgoals, and checks proofs with the Kimina Lean server.
Abstract
Recent advances in large language models (LLMs) and LLM-based agents have substantially improved the capabilities of automated theorem proving. However, for problems that require complex mathematical reasoning, current systems seldom succeed in their initial attempt, necessitating iterative adjustments to their proof strategies. Existing approaches for handling failed attempts typically either iteratively fix errors within the proof or discard the entire proof and regenerate it from scratch. The former leads to progressively longer contexts, which degrade the model's ability to attend to the remaining unresolved subproblems, while the latter is inefficient, as it may abandon mostly correct reasoning due to localized errors. To address this dilemma, we present MechMath, an agent system centered on a Sorrifier-driven formal decomposition paradigm. By leveraging the sorry placeholder in Lean to precisely isolate unresolved subgoals while preserving the surrounding verified proof structure, MechMath extracts each failed subproblem into a clean, self-contained context and resolves it independently. This avoids both the waste of full regeneration and the excessive context length induced by repeated repairs. Experimental results on challenging mathematical competition benchmarks, including IMO 2025, Putnam 2025, miniF2F, and a subset of ProverBench, demonstrate that our agent achieves significant advantages in proving efficiency.
Problem
LLM-based formal provers rarely succeed on the first attempt at hard problems. Repeatedly repairing a proof bloats the context, while regenerating it from scratch throws away mostly correct reasoning.
Approach
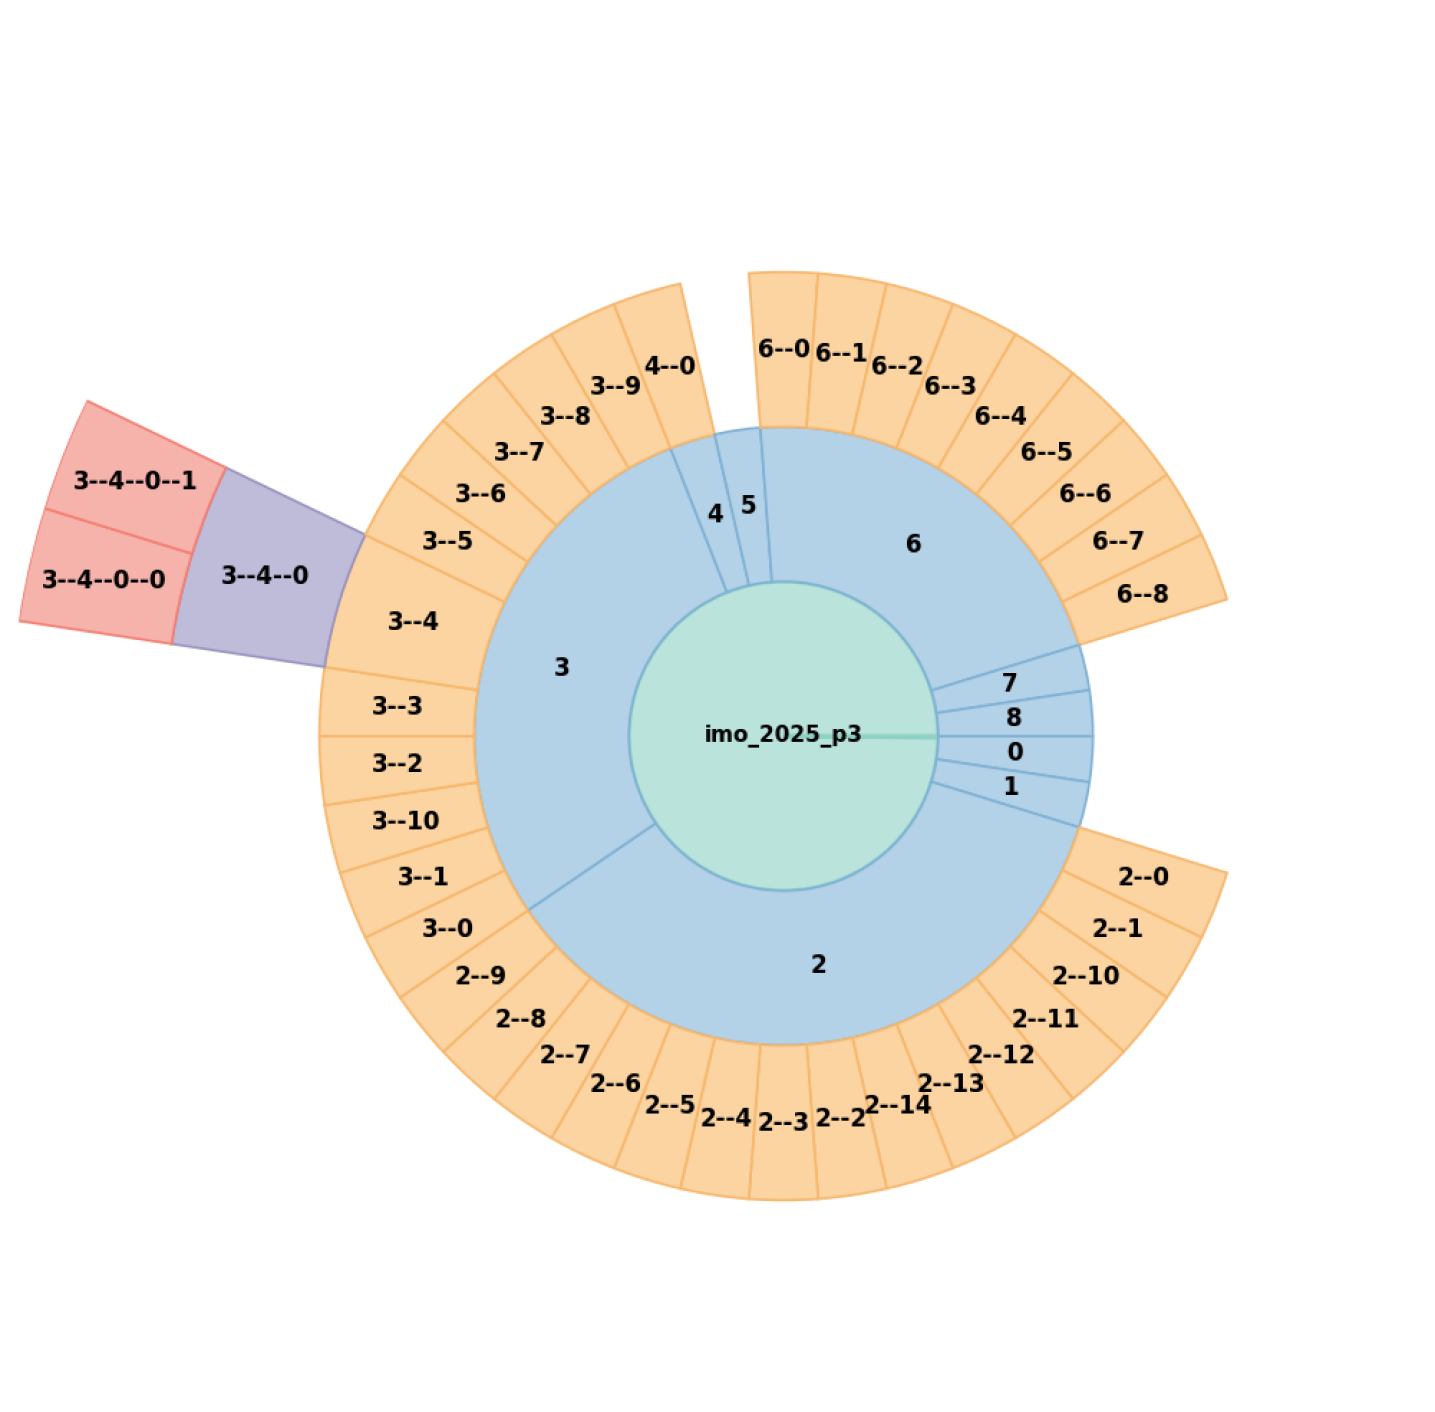
The agent generates and verifies an informal proof, translates it into Lean, and revises it using Lean compiler feedback. If revisions keep failing, a Sorrifier replaces the erroneous blocks with sorry placeholders. It then extracts the goal state at each sorry as a self-contained subtheorem and solves each one recursively with the same pipeline. Gemini-3.1-Pro serves as reasoner, verifier and prover, with LeanDex and Loogle used for theorem retrieval.
Figure 2: Workflow of Mechanic. (1) An informal solution is generated, verified and iteratively improved through a feedback loop. (2) The final informal solution is then translated into a formal proof, which is further revised based on Lean’s feedback. (3) If the proof continues to fail after several revisions, it is transformed into a sorried proof to extract subgoals. (4) Each resulting subgoal
Results
The agent was evaluated on Putnam 2025, IMO 2025, miniF2F and a ProverBench subset. On 11 of the 12 Putnam 2025 problems it averaged 114 minutes and $18.5, compared with 165–196 minutes for the Seed, Axiom and Numina baselines. It also produced shorter proofs than Seed on IMO 2025 P1, P3 and P4.