RMA: Context-Orchestrated Research Math Agents
Zelin Zhao, Bo Yuan, Yuchen Zhu, Jaemoo Choi, Yongxin Chen
cs.AI
May 20, 2026 · v2
cs.LG
TL;DR
Evaluates an agentic math framework by producing Lean 4 proofs for Formal Conjectures targets, verified by the Lean kernel under pinned Mathlib environments.
Abstract
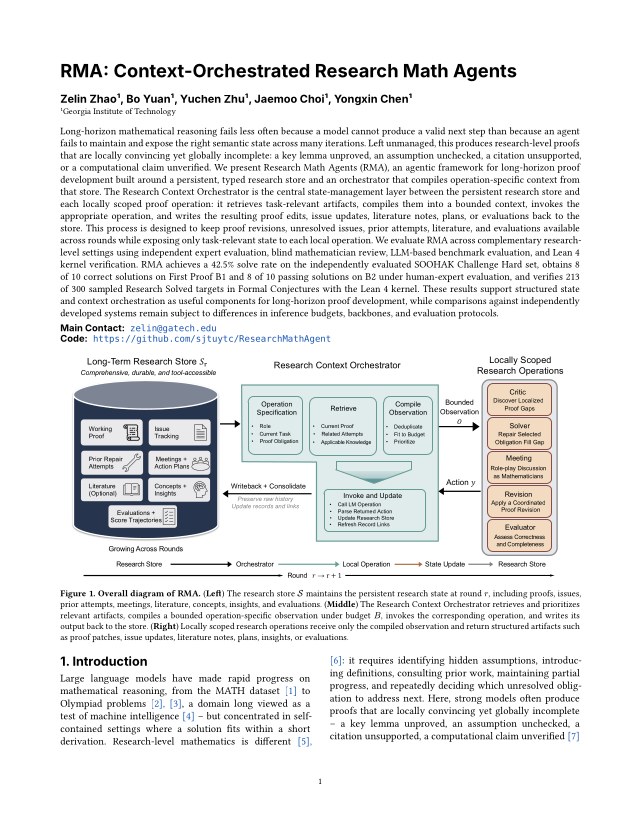
Long-horizon mathematical reasoning fails less often because a model cannot produce a valid next step than because an agent fails to maintain and expose the right semantic state across many iterations. Left unmanaged, this produces research-level proofs that are locally convincing yet globally incomplete: a key lemma unproved, an assumption unchecked, a citation unsupported, or a computational claim unverified. We present Research Math Agents (RMA), an agentic framework for long-horizon proof development built around a persistent, typed research store and an orchestrator that compiles operation-specific context from that store. The Research Context Orchestrator is the central state-management layer between the persistent research store and each locally scoped proof operation: it retrieves task-relevant artifacts, compiles them into a bounded context, invokes the appropriate operation, and writes the resulting proof edits, issue updates, literature notes, plans, or evaluations back to the store. This process is designed to keep proof revisions, unresolved issues, prior attempts, literature, and evaluations available across rounds while exposing only task-relevant state to each local operation. We evaluate RMA across complementary research-level settings using independent expert evaluation, blind mathematician review, LLM-based benchmark evaluation, and Lean 4 kernel verification. RMA achieves a 42.5% solve rate on the independently evaluated SOOHAK Challenge Hard set, obtains 8 of 10 correct solutions on First Proof B1 and 8 of 10 passing solutions on B2 under human-expert evaluation, and verifies 213 of 300 sampled Research Solved targets in Formal Conjectures with the Lean 4 kernel.
Problem
Long-horizon research-level mathematical reasoning by LLM agents often yields proofs that look convincing locally but are globally incomplete, with unproved lemmas, unchecked assumptions, or unverified claims. The underlying failure is in keeping the right semantic state across many iterations.
Approach
RMA is an agentic framework built around a persistent, typed research store and a Research Context Orchestrator. For each locally scoped proof operation, the orchestrator retrieves the relevant artifacts, compiles them into a bounded context, invokes the operation, and writes the resulting proof edits, issues, literature notes, plans, or evaluations back to the store. Evaluation combines expert review, blind mathematician review, LLM-judged benchmarks, and Lean 4 kernel verification. In the Lean evaluation, proofs using sorry, custom axioms, or native_decide are rejected.
Results
RMA reaches a 42.5% solve rate on SOOHAK Challenge Hard and gets 8/10 solutions on First Proof B1 and 8/10 on B2 under human-expert evaluation. On 300 sampled Formal Conjectures Research Solved targets, it verifies 213 with the Lean 4 kernel, compared with 193 for SeedProver and 121 for direct Claude Opus 4.8.
| Method | Setting | Verified |
|---|
| RMA (Opus 4.8) | agentic | 213/300 |
| Seed-Prover | prover | 193/300 |
| Hilbert | prover | 164/300 |
| NanoProof | prover | 135/300 |
| Opus 4.8 direct | direct | 121/300 |
Formal Conjectures Research Solved, Lean 4 kernel verification (300 sampled targets)