Builds a Lean 4 and Mathlib autoformalization benchmark that checks semantic alignment by proving Lean implications between generated statements and auxiliary shadow theorems.
Abstract
Autoformalization translates informal mathematical theorems into code for proof assistants such as Lean. A central challenge is that current evaluation metrics can accept type-correct but misaligned statements or reject correct statements written in a different formulation. Inspired by Pass@$k$, we propose SA-Pass (*Semantic Alignment Pass*), which tests formal statements using auxiliary statements called *shadows* that characterize the intended statement. A generated statement receives full credit only when it compiles, implies each shadow (forward check), and is implied by their conjunction (backward check). We instantiate SA-Pass in ShadowBench, a Lean 4 full autoformalization benchmark of 178 postgraduate- to research-level problems spanning eight mathematical areas. Claude Code (Opus 4.8) with Numina-Lean-Agent reaches $61.8\%$ compile rate and $11.2\%$ SA-Pass. Across outputs generated by six agentic configurations, SA-Pass achieves $98.8\%$ binary agreement with expert judgments. An early version of ShadowBench served as the benchmark for Track 4 of the ICML 2026 AI4Math Challenge.
Problem
Automatic evaluation of autoformalization is unreliable. Compile rate accepts type-correct but misaligned statements, and reference-equivalence or lexical metrics reject correct alternative formulations.
Approach
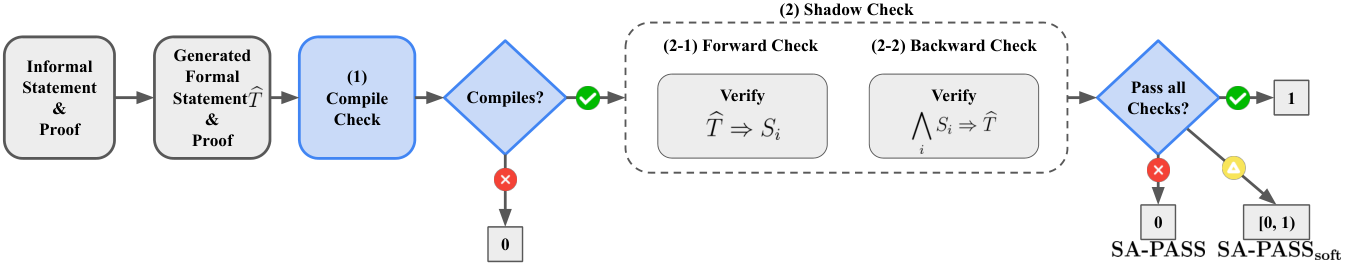
SA-Pass scores a generated Lean statement using auxiliary 'shadow' statements whose conjunction is equivalent to the intended theorem. A generated statement passes only if it compiles, implies each shadow (forward check), and is implied by the conjunction of the shadows (backward check). The checks are carried out in Lean, and a soft variant gives partial credit. ShadowBench instantiates the metric with 178 postgraduate- to research-level problems across eight areas, using LLM-drafted shadows that Lean verifies for completeness and experts review.
Figure 3: Evaluation procedure for SA-Pass and SA-Pass soft on one ShadowBench problem.
Results
Claude Code (Opus 4.8) with Numina-Lean-Agent reaches 61.8% compile rate but only 11.2% SA-Pass. Against expert judgments, SA-Pass achieves 0.988 agreement and 0.964 F1, outperforming compile rate, BLEU, BEq+, and LLM-as-judge.
Metric
Precision
Recall
F1
Agreement
Compile
0.178
1.000
0.302
0.178
BLEU
0.234
0.674
0.347
0.550
BEq+
0.400
0.186
0.254
0.806
SA-Pass
1.000
0.930
0.964
0.988
Agreement of automatic metrics with expert judgments (selected rows)